Personalization Evaluation
900+ personalization evaluation tasks in one week
How Digitive mobilised 70+ credentialed specialists in under 48 hours to rescue a frontier-model deadline — with 100% completion and 100% on-time submission.
900+
P13n evaluation cases delivered
70+
Credentialed specialists
<48h
Sourced, consented & calibrated
90%+
First-pass quality
Client context
A frontier AI personalization (P13n) programme needed a large batch of evaluation cases completed inside a single week. The deadline was fixed and non-negotiable: downstream model work depended on the data landing on time. The requirement was not simply volume — each case was a structured, multi-part evaluation that could not be rushed, and the specialist profile was narrow: verified product usage history within a specific date window, a personal account configured to expose personalization behaviour, signed consent to a sensitive data-access protocol, and the analytical ability to write substantive evaluation rationales. Most vendors need weeks to assemble that combination. The client needed it in days.
Challenge
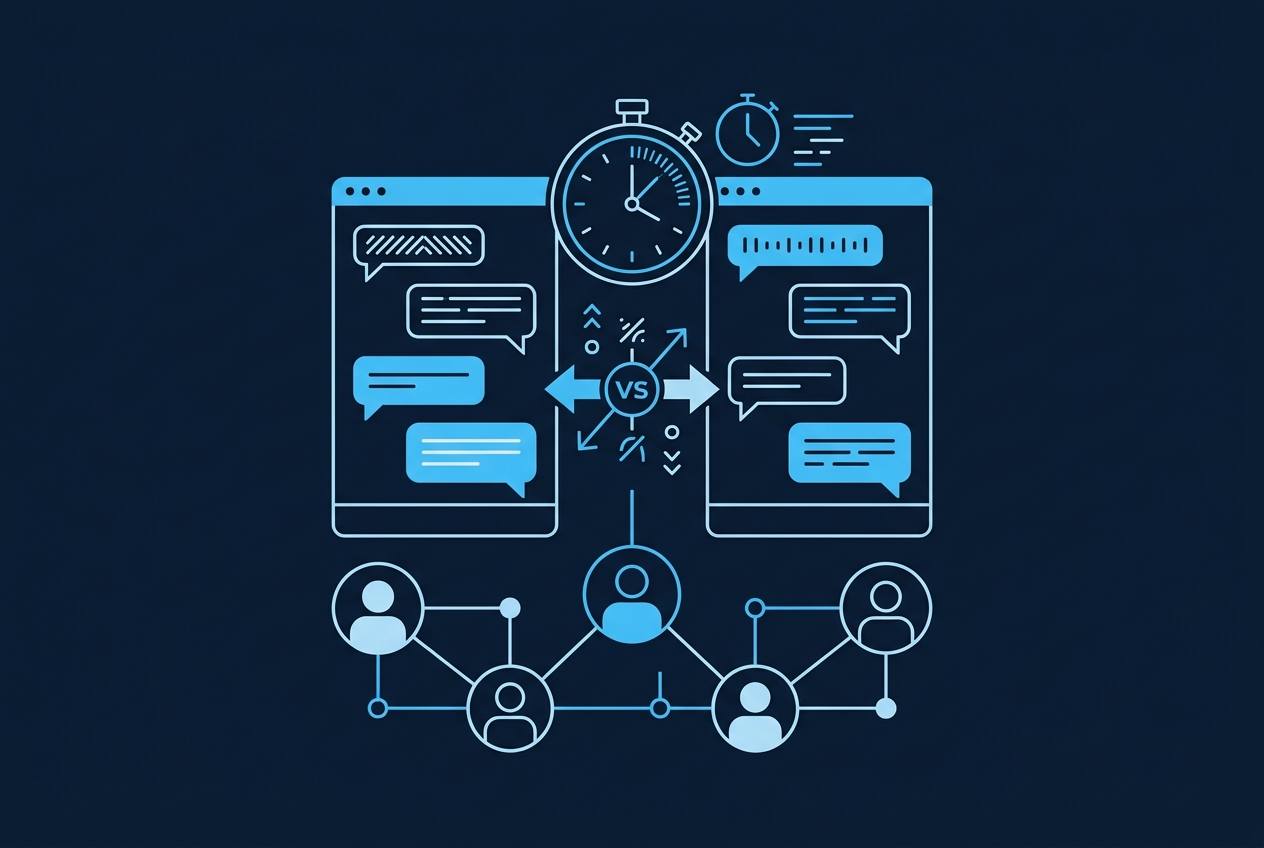
A single P13n case is a controlled experiment run by hand: author a prompt matching an assigned use case and personalization classification, run the identical opening prompt through a test build and a control model across up to five turns, capture a debug file for every turn, and delete conversations between models so no context leaks — otherwise the comparison is scientifically worthless. Each model was then evaluated independently (personalization triggered when it should be, personal data used accurately, relevant context not missed) with turn numbers cited, followed by a side-by-side preference supported by a 150+ word rationale. At ~1.5 hours per case, 900+ cases meant roughly 1,350 specialist hours — inside seven days, at a quality bar where one missing debug file invalidates the case entirely.
What we delivered
Day 0–1
Mobilised from a pre-vetted bench, not a recruitment pipeline: activated our specialist hotlist filtered by eligibility and prior comparable work, contacted in waves, and deliberately over-recruited by 25–30% to absorb compressed-start fallout
Day 1–2
Consent and configuration as a hard gate: no task access until signed personalization consent, verified eligibility, executed paperwork, and a debug-panel-verified account setup were all complete
Day 2
Trained and calibrated 70+ specialists at speed: structured training module with a mandatory knowledge check, live kickoff, and 100% review of every specialist's first 2–3 cases with individual feedback inside 24–48 hours
Day 2–7
Production with daily pace control: morning assignment against volume targets, midday throughput checks, end-of-day counts with blocker resolution, staffed support channel, and pre-trained standby specialists activated the moment anyone fell behind
Throughout
QC as a system, not an inspection: every case reviewed against a structured 12-point checklist (matched debug files, identical opening prompts, cited turn numbers, rationale word counts, logical consistency), with return reasons tracked as a taxonomy and recurring issues fixed via whole-team re-briefs
Outcome
100%
Completion across the batch
100%
On-time submission vs. SLA
90%+
First-pass quality held
1,350
Specialist hours in 7 days
900+ complex evaluation cases delivered inside one week, in full, on time. First-pass quality held at 90%+ across the batch, with 100% completion and 100% on-time submission against the agreed SLA. The programme's deadline was met without a quality concession — and without the client absorbing the coordination load of managing 70 individual contributors. The week was won before it started: a pre-vetted, pre-briefed bench compressed a multi-week sourcing cycle into days.
Want the full picture?
Detailed methodologies, delivery models, staffing tiers, and every case study in one PDF. No sales call required.
More case studies
150+ specialists · 85%+ IAA · 60-day scale-up
RLHF pipeline for a frontier LLM lab
How we stood up a 150-person annotation team in eight weeks and lifted preference-ranking agreement past 85%.
Read case study18 languages · 400+ native evaluators · 96% on-time
Multilingual output evaluation for a global consumer AI
Native-speaker linguistic and cultural evaluation across 18 languages — beyond back-translation, beyond BLEU.
Read case study2,300+ adversarial prompts · 40+ languages · 118 critical findings
Frontier-model red team for a policy-critical AI deployment
Structured adversarial testing across jailbreaks, prompt injection, and policy stress — with severity-ranked findings the safety team could act on.
Read case study