RLHF & SFT
RLHF pipeline for a frontier LLM lab
How we stood up a 150-person annotation team in eight weeks and lifted preference-ranking agreement past 85%.
150+
PhD & Masters annotators
85%+
Inter-annotator agreement
60 d
From kickoff to full scale
4×
Throughput vs. baseline vendor
Client context
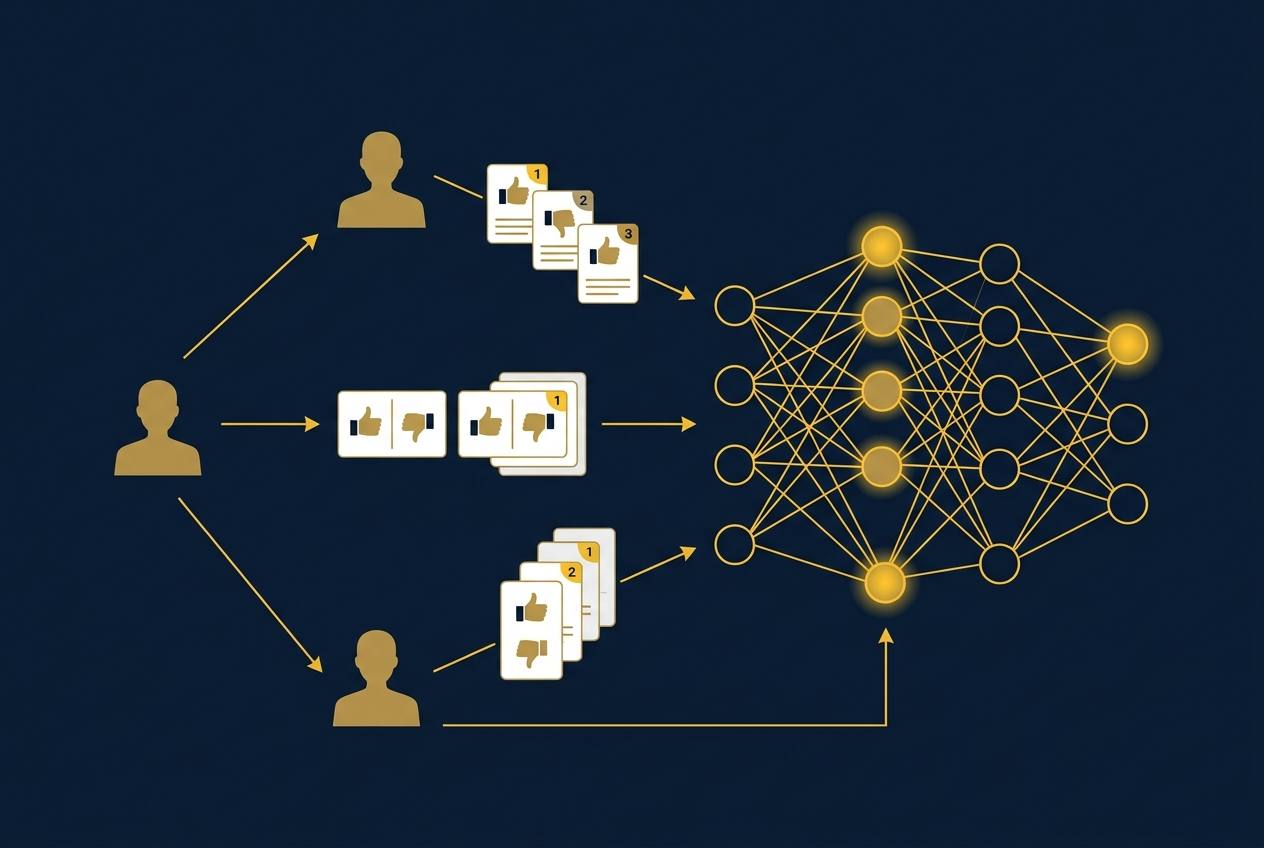
A frontier AI lab shipping a new flagship model needed to scale their reinforcement-learning-from-human-feedback (RLHF) pipeline from a small in-house team to production-grade throughput ahead of a launch window. Existing crowd-sourced vendors were producing preference data with inter-annotator agreement below 70% — high enough to train a model, low enough to leave real capability gains on the table.
Challenge
Recruit, vet, and onboard 150+ subject-matter annotators across code, math, safety, and reasoning within 60 days, while holding annotator agreement above 85% and maintaining a full audit trail per response for every preference pair delivered.
What we delivered
Step 1
Sourced 150 vetted specialists from our 2,000+ PhD / Masters network — 40% with published research in ML, reasoning, or applied math
Step 2
Built a domain-tiered annotation pipeline: 4 skill tiers with escalation paths, calibration rounds, and blind gold-set injection at 5% sample rate
Step 3
Deployed dedicated program managers, senior QC leads, and a full governance layer with per-annotator quality dashboards
Step 4
Ran weekly calibration syncs with the client's eval team; re-graded the bottom-quartile annotators every 14 days
Outcome
150+
PhD & Masters annotators
85%+
Inter-annotator agreement
60 d
From kickoff to full scale
4×
Throughput vs. baseline vendor
Preference-ranking IAA reached 85–89% within the first two calibration cycles. Delivery ramped to 12,000+ ranked pairs per week by day 45. The pipeline is now the client's primary RLHF vendor for their next-generation model, and the engagement has expanded into red-teaming and SFT data generation.
Want the full picture?
Detailed methodologies, delivery models, staffing tiers, and every case study in one PDF. No sales call required.
More case studies
18 languages · 400+ native evaluators · 96% on-time
Multilingual output evaluation for a global consumer AI
Native-speaker linguistic and cultural evaluation across 18 languages — beyond back-translation, beyond BLEU.
Read case study2,300+ adversarial prompts · 40+ languages · 118 critical findings
Frontier-model red team for a policy-critical AI deployment
Structured adversarial testing across jailbreaks, prompt injection, and policy stress — with severity-ranked findings the safety team could act on.
Read case study900+ eval cases · 70+ specialists · 1 week
900+ personalization evaluation tasks in one week
How Digitive mobilised 70+ credentialed specialists in under 48 hours to rescue a frontier-model deadline — with 100% completion and 100% on-time submission.
Read case study